THE SCHOOL OF KAMOS
Connecting Real-world Dev & Academic Intelligence with Intuitive Metaphors
Bridging the Invisible 1-Byte Gap: Anatomy of Memory Alignment Connecting GPUs and AI
Intricate gears of ultra-high-speed parallel processing viewed through a 160-byte boundary
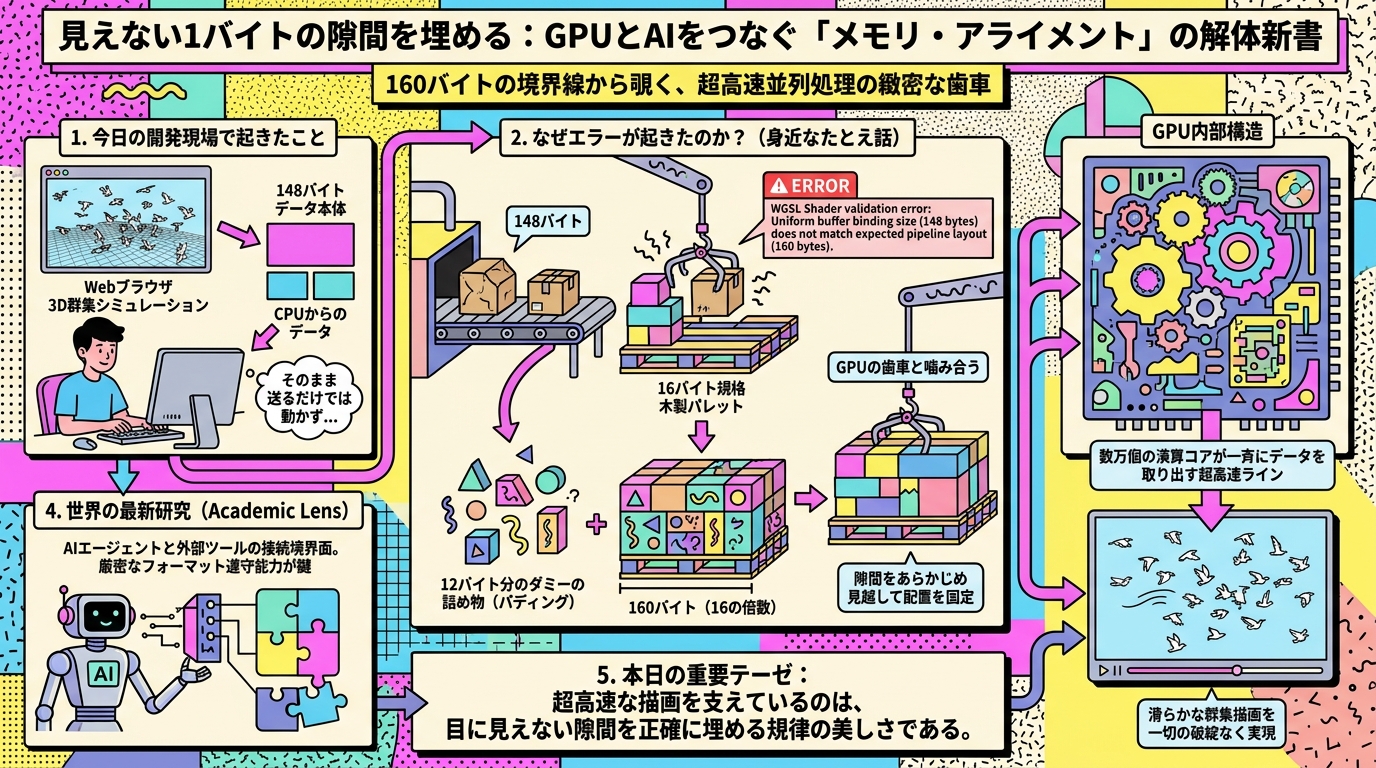
A 3D crowd simulation featuring thousands of birds swirling across a web browser. On the surface, the process—rendering a flock—appears deceptively simple. Yet, beneath the skin, at the millisecond moment data travels from CPU to GPU, a rigorous handoff takes place where not even a 1-byte misalignment is tolerated. Why couldn't the data simply be sent as-is, and why was a strict size adjustment of 160 bytes required?
Visualizing the GPU's internal structure like an X-ray reveals an ultra-high-speed line where tens of thousands of compute cores retrieve data simultaneously. This resembles a cargo terminal where goods are loaded using standardized wooden pallets. The width of the pallet, designed to allow hardware to grab data at maximum speed, is fixed at 16 bytes. Even if the core payload you wish to transmit is 148 bytes, the crane cannot recognize the cargo if there is any fractional remainder that violates the pallet standard. Only by neatly packing 12 bytes of dummy padding into the gap to make it 160 bytes—a multiple of 16—does the data mesh smoothly with the GPU's gears.
In our development, to tame this rule of invisible gaps, we established a design that matches the data layout and boundaries to the millimeter between the shader's receiving structure and the JavaScript buffer generation code. Even when an AI auto-generates a program with correct numerical calculation logic, it frequently halts by overlooking such hardware-specific physical alignment rules. By anticipating these internal alignment gaps in advance and fixing the layout, we achieved smooth crowd rendering on the web browser without a single breakdown.
"Beneath ultra-high-speed rendering lies the beauty of discipline, precisely filling invisible gaps."Key Takeaway
📖 1-Minute Lexicon
A shared memory area used to batch-deliver configuration values shared across the entire screen, such as camera position and elapsed time, from the CPU to the GPU.
A rule that aligns data at positions that are multiples of a designated boundary (such as 16 bytes) so that hardware can read data at maximum speed.
Anatomical Structure of GPU Memory Alignment
Live Frontier Pulse: Real-World AI Trends
Analysis Report on Unexpected Behaviors and Vulnerabilities Lurking in Autonomous Multi-Agent Systems
A technical report using red-team verification to elucidate the mechanisms by which unexpected coordination breakdowns, communication loops, and security vulnerabilities arise in environments where multiple autonomous AI agents interact with one another.
How Does This Connect to Global Frontier Research?
This research examines how accurately small reasoning models can adhere to specified argument types and data structures when calling external tools and functions as autonomous agents. Just as GPUs demand 16-byte boundary alignment, when an AI agent connects with real-world systems, a mismatch in even a single data format will halt the entire process. It demonstrates that beyond the model's reasoning capabilities, strict format compliance at the connection interface is a critical key determining the stability of practical systems.
In graphics processing such as WebGPU, why is it necessary to match the entire buffer size to 160 bytes even if the actual data is 148 bytes?
Past School Paper Backnumbers
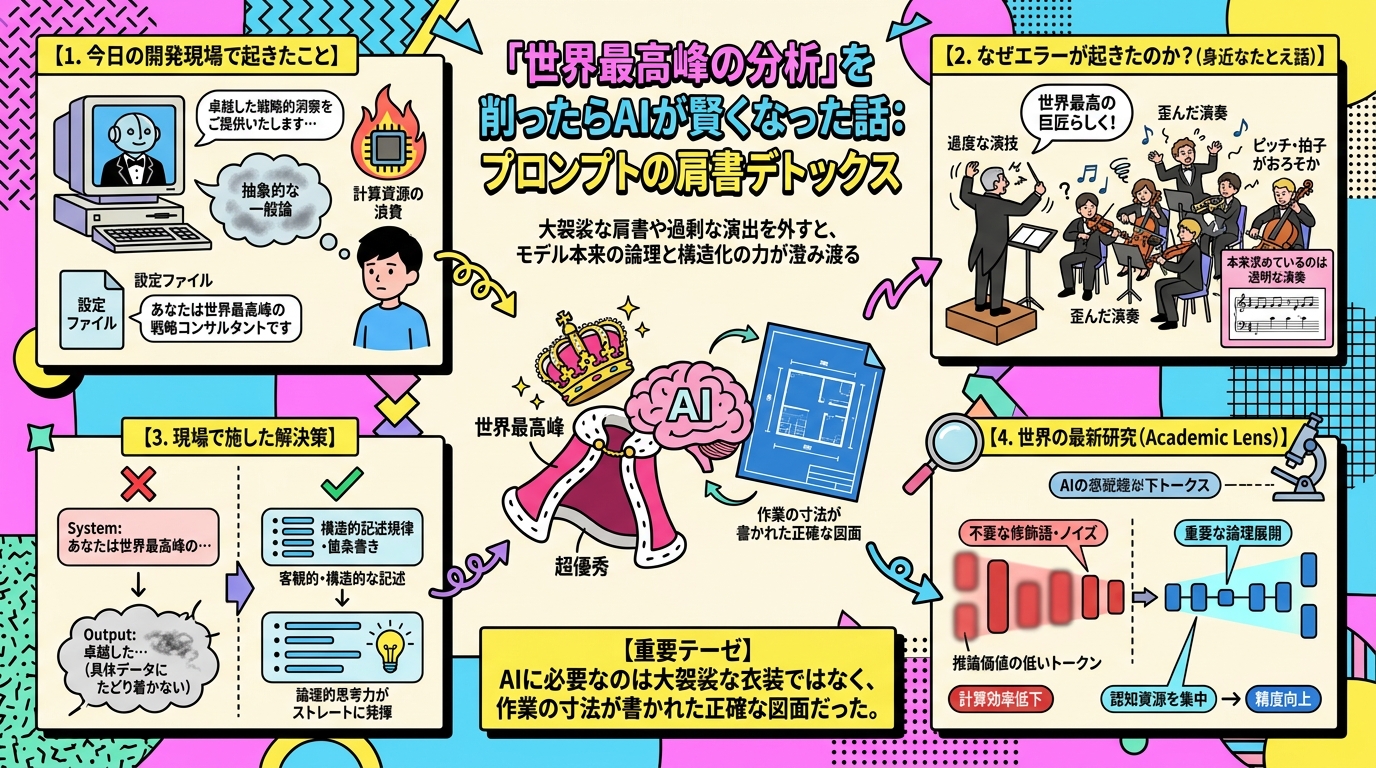
How AI Grew Smarter Once We Stripped 'World-Class Analysis': The Prompt Title Detox
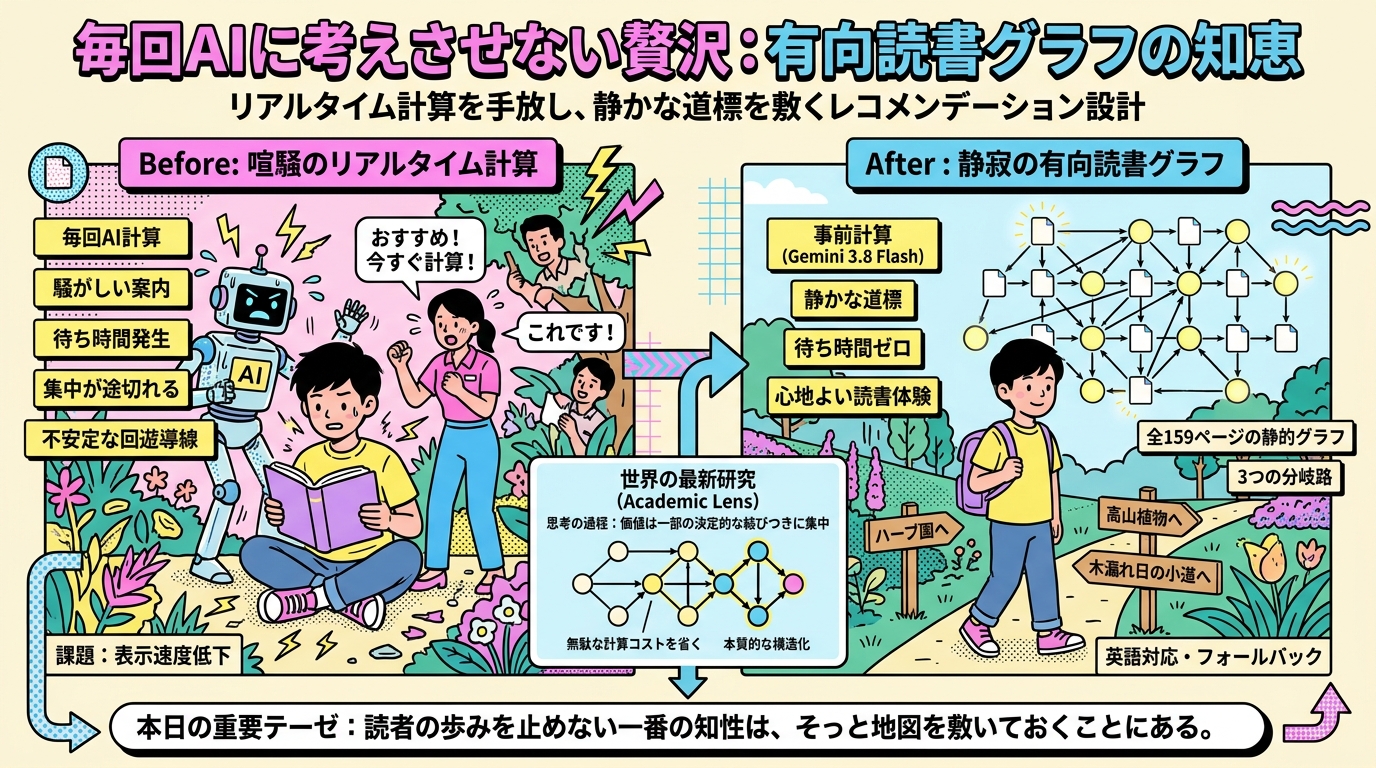
The Luxury of Not Asking AI Every Time: The Wisdom of a 'Directed Reading Graph' Connecting 159 Pages
Clearing the AI's Vision by Erasing the Grading Rule: The High Leverage of Subtracting a Single Line
Don't Be Deceived by a 'Connection Successful' Response: Lessons in Live Content Verification from Delegating Quality Checks to AI
The Art of Surveying the Field, Narrowing Down, and Discerning the Branches
Can Expressive Richness Coexist with Nimble Performance? How Scoped Animation Control Solved the "Fluctuation" Dilemma
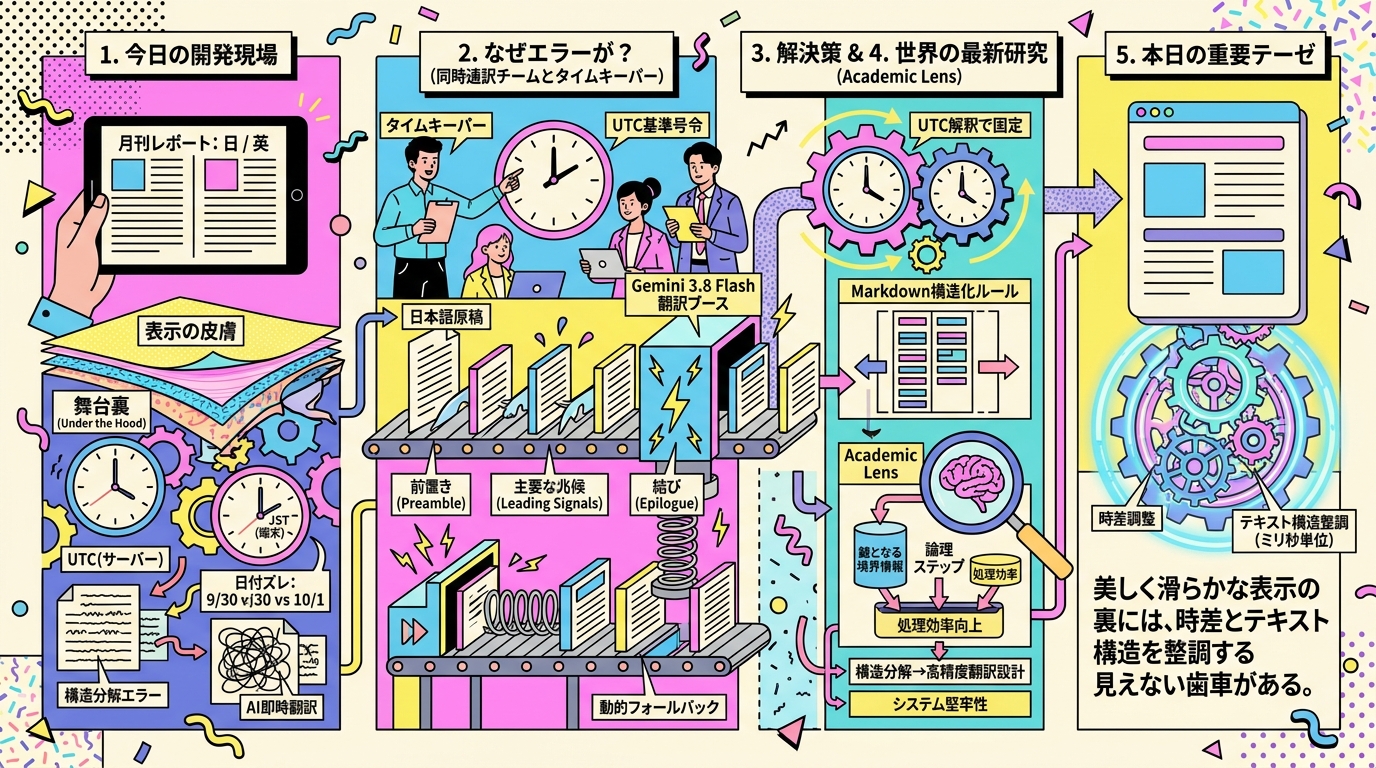
The Gears of Timezones and Translation Stirring Behind the Screen: An X-Ray of the Bilingual Automated Delivery Pipeline
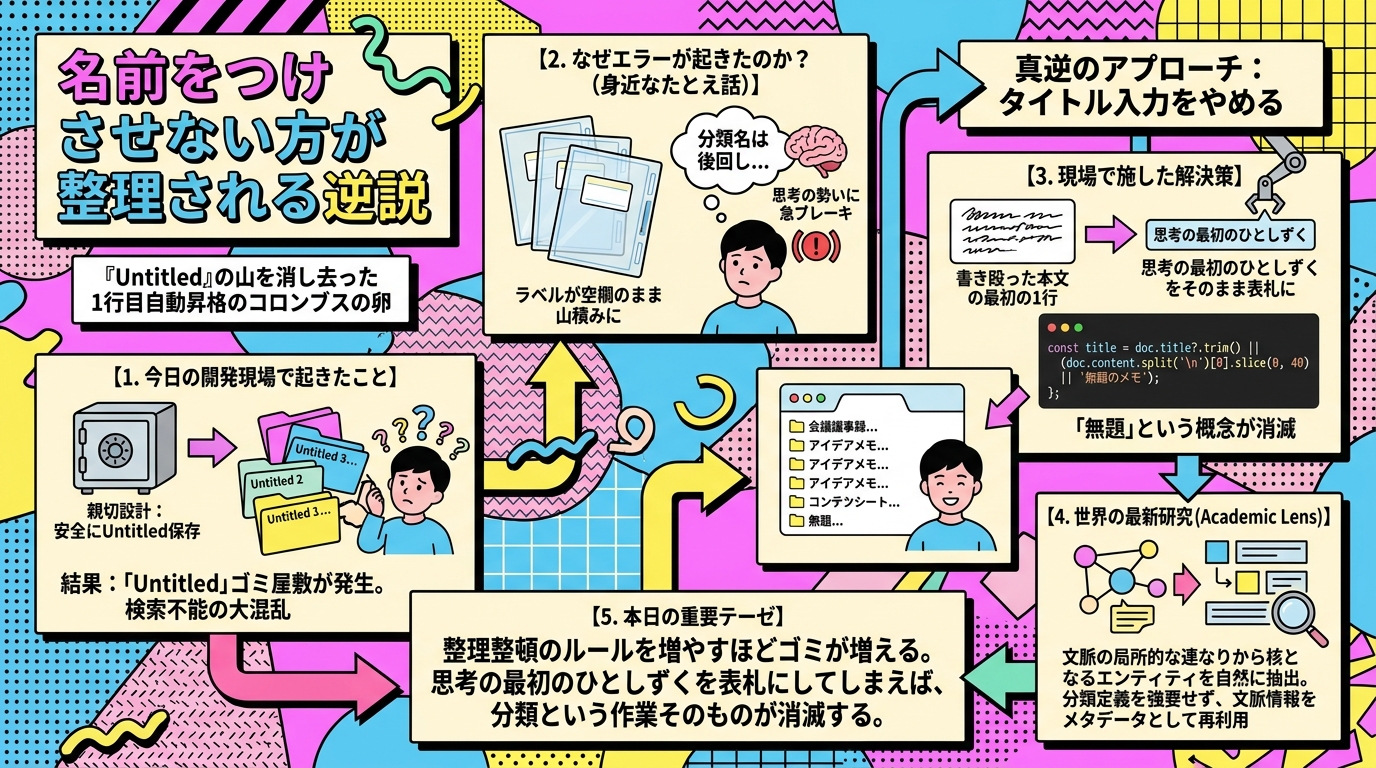
The Paradox of Order: Why Not Asking for Titles Actually Cleans the Clutter
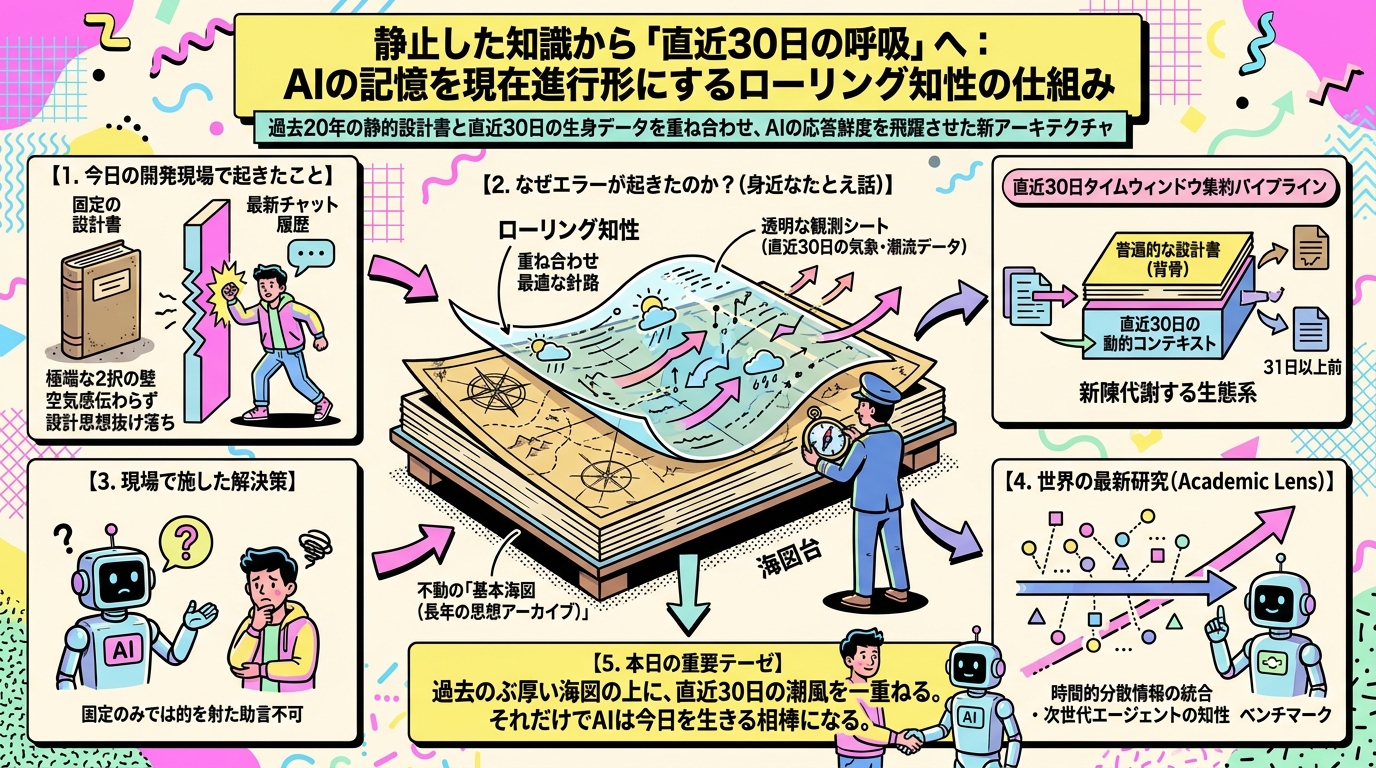
From Static Knowledge to the Pulse of the Last 30 Days: How Rolling Intelligence Keeps AI Memory in the Present Tense
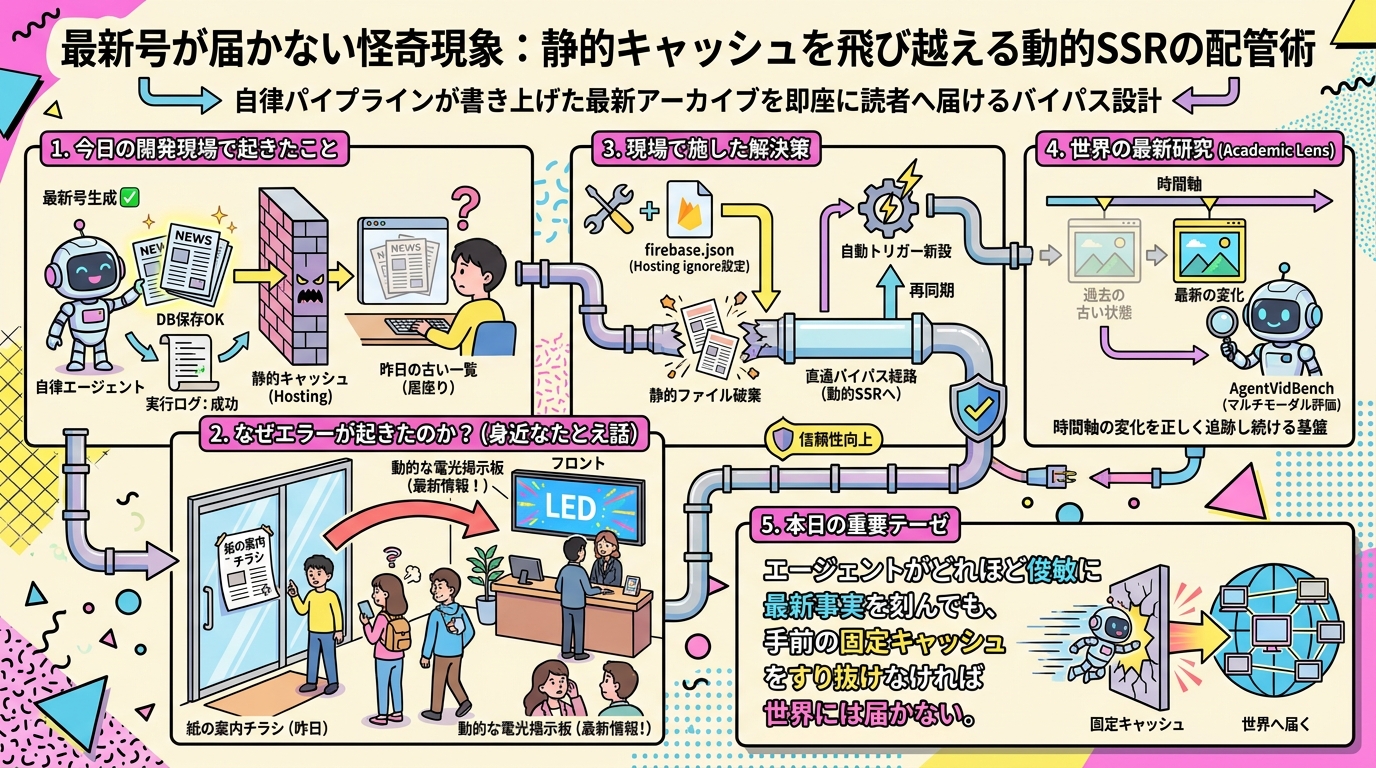
The Mystery of the Missing Issue: Plumbing Dynamic SSR to Bypass Static Cache
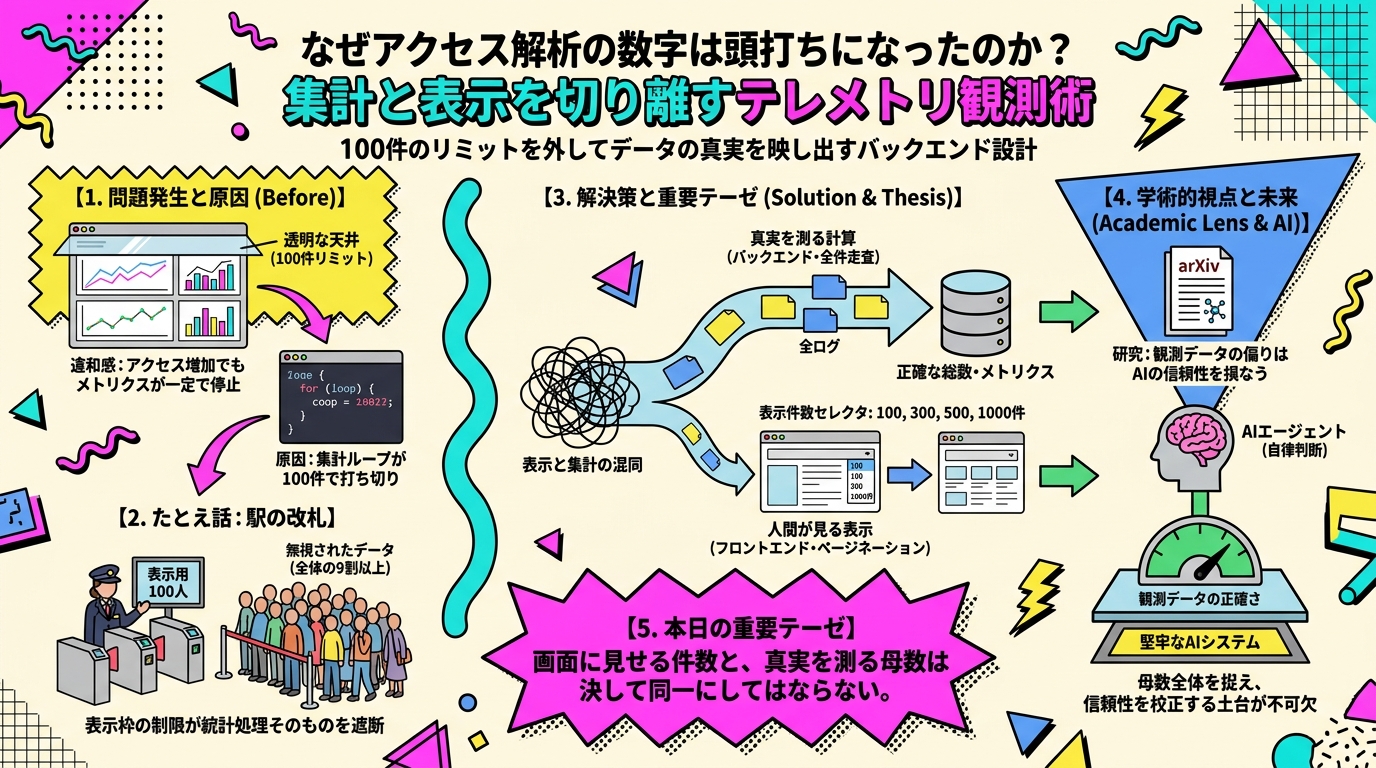
Why Did Access Analytics Hit an Artificial Ceiling? Telemetry Observability by Decoupling Aggregation from Display
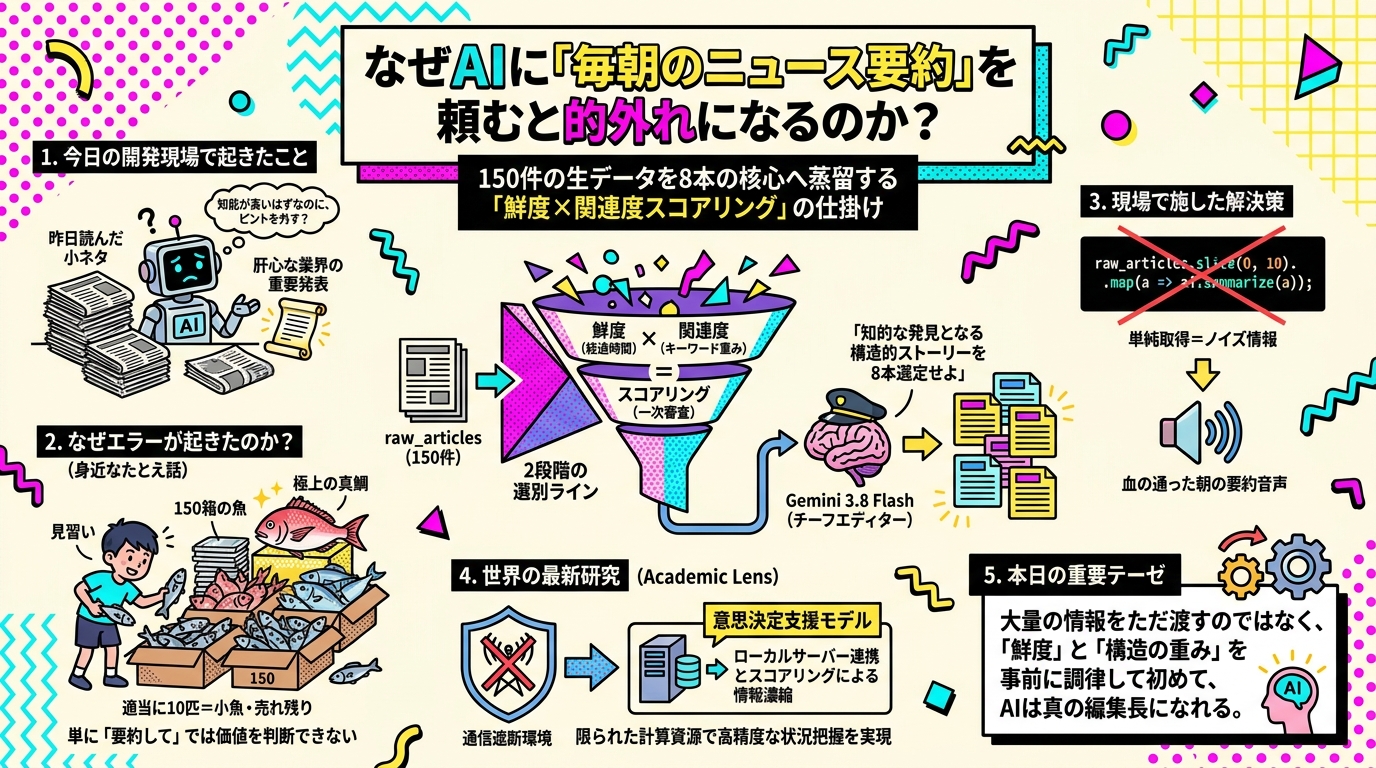
Why Asking AI to Summarize 'Morning News' Always Misses the Mark
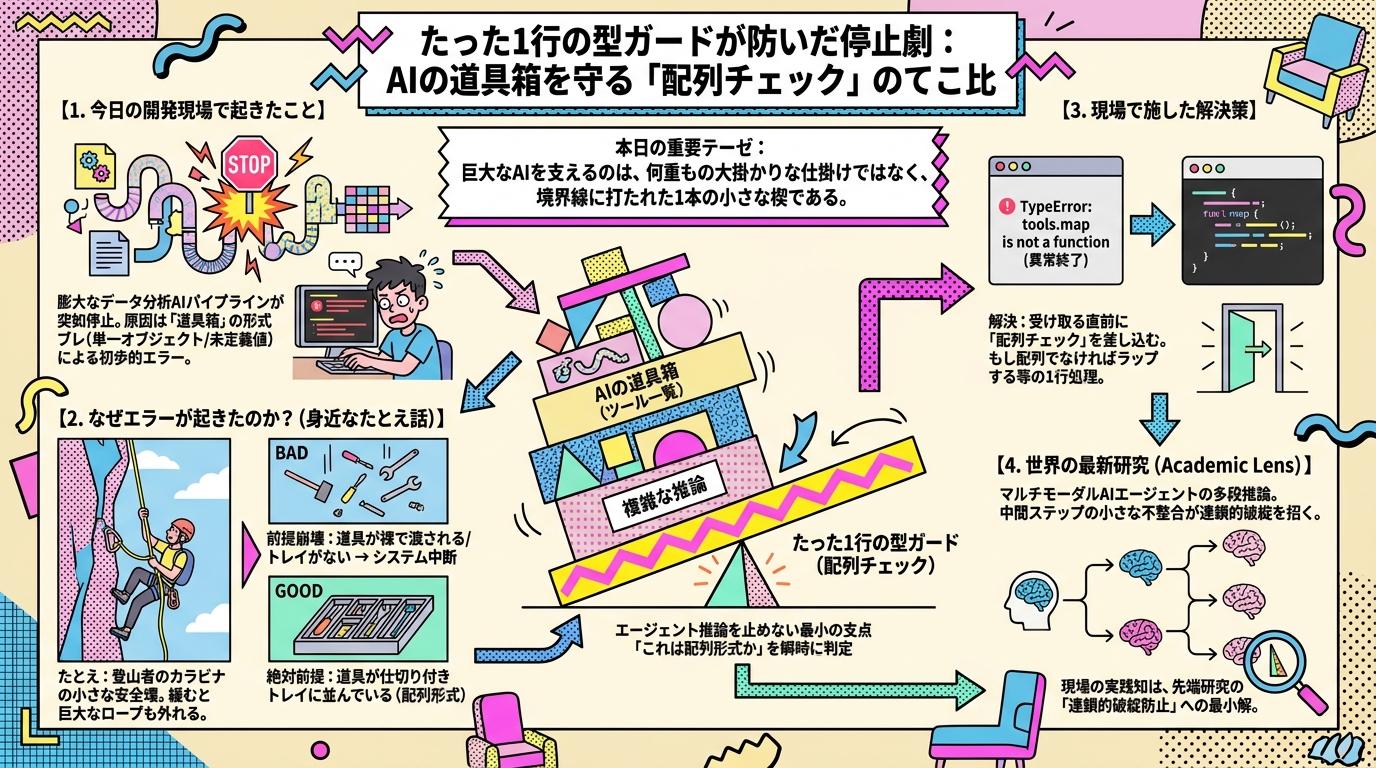
A Single-Line Type Guard That Prevented a Crash: The Leverage Ratio of 'Array Checks' in Protecting the AI's Toolbox